Expediting FEP+ model optimization for challenging systems with a fully automated, machine learning-driven workflow
JUN 25, 2024
Expediting FEP+ model optimization for challenging systems with a fully automated, machine learning-driven workflow


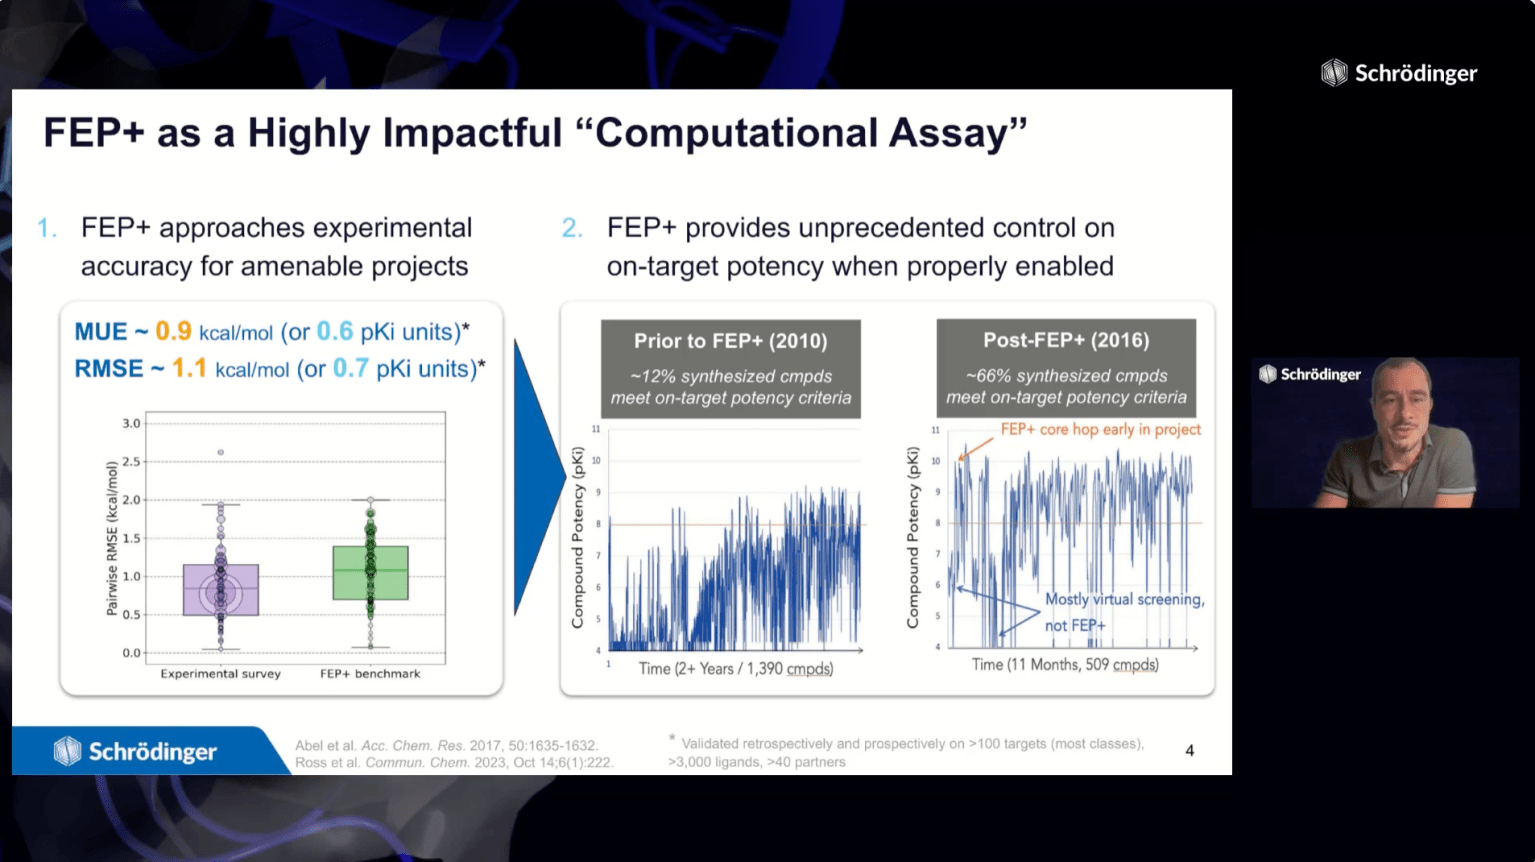
FEP+ is a powerful predictive technology in drug discovery – with applications from hit discovery through lead optimization. A critical first step in deploying FEP+ is to validate and optimize the model for the protein-ligand system of interest. While some systems perform well with out-of-the-box FEP+ settings, others require manual protocol refinement.
In this webinar, we will introduce Schrödinger’s FEP+ Protocol Builder, an automated machine learning workflow for FEP+ model optimization. This workflow is designed for systems with insufficient predictive accuracy using default settings or after initial manual protocol optimization attempts. FEP+ Protocol Builder saves researcher time and increases the chances of successfully enabling FEP+ by efficiently identifying an optimized predictive model for your system of interest.
Join us as we share key features of FEP+ Protocol Builder and highlight case studies that have shown success utilizing the technology to accelerate projects.
Highlights:
- Overview of FEP+ Protocol Builder technology, which uses an Active Learning workflow to iteratively search the protocol parameter space to develop accurate FEP+ protocols
- Case studies on effective prospective use of protocols generated by FEP+ Protocol Builder in drug discovery programs
- Comparison of time efficiency between manual and automated FEP+ optimization
- Details on requirements and services options to leverage the technology in your own program
- Overview of the different options to enable FEP+ at almost all levels of structural information for your protein-ligand system of interest
Our Speakers
Jeremie Vendome
Senior Director, Applications Science, Schrödinger
Dr. Jeremie Vendome, senior director of applications science, joined Schrödinger in 2015. He received his PhD from the Ecole Normale Superieure in France and completed his training at Columbia University in the lab of Prof. Barry Honig, where he worked on various problems related to protein-protein interaction energetics and specificity by combining computational approaches and experiments. Prior to joining Schrödinger, Jeremie acquired 10+ years of drug discovery experience both as a computational chemist in the industry and as the head of a CADD collaborative platform at Columbia Medical Center. At Schrödinger, he has held several roles of increasing responsibility and has continuously been at the interface between the company’s latest technological developments and their applications in active drug discovery projects. Most recently, Jeremie has been spearheading Schrödinger’s research enablement initiative, meant to advance drug discovery programs though key stages by providing access to our latest technologies and workflows at scale as a collaborative service.
Jordan Epstein
Product Manager, Schrödinger
Jordan Epstein joined Schrödinger in 2017 after studying Chemistry at New York University. Upon joining Schrödinger as a software developer, he worked on products such as FEP+, Desmond, and LiveDesign. More recently, he transitioned into his role as product manager where he has helped to see FEP+ Protocol Builder to its full release.

Sathesh Bhat
Executive Director, Therapeutics Group, Schrödinger
Sathesh Bhat, Ph.D., executive director in the therapeutics group, joined Schrödinger in 2011. He is responsible for overseeing computational chemistry efforts on internal and partnered drug discovery programs at Schrödinger. Previously, Sathesh worked at both Merck and Eli Lilly leading computational efforts in several drug discovery programs. He obtained his Ph.D. from McGill University, which involved developing structure-based methods to predict binding free energies. Sathesh has co-authored multiple patents and publications and continues to publish on a wide variety of topics in computational chemistry.
Machine learning force field ranking of candidate solid electrolyte interphase structures in Li-ion batteries
Trends in modern hit discovery: How your ultra-large screens can benefit from machine learning

FEB 2, 2022
Trends in modern hit discovery: How your ultra-large screens can benefit from machine learning
Speaker:
Matt Repasky
Senior Vice President
Abstract:
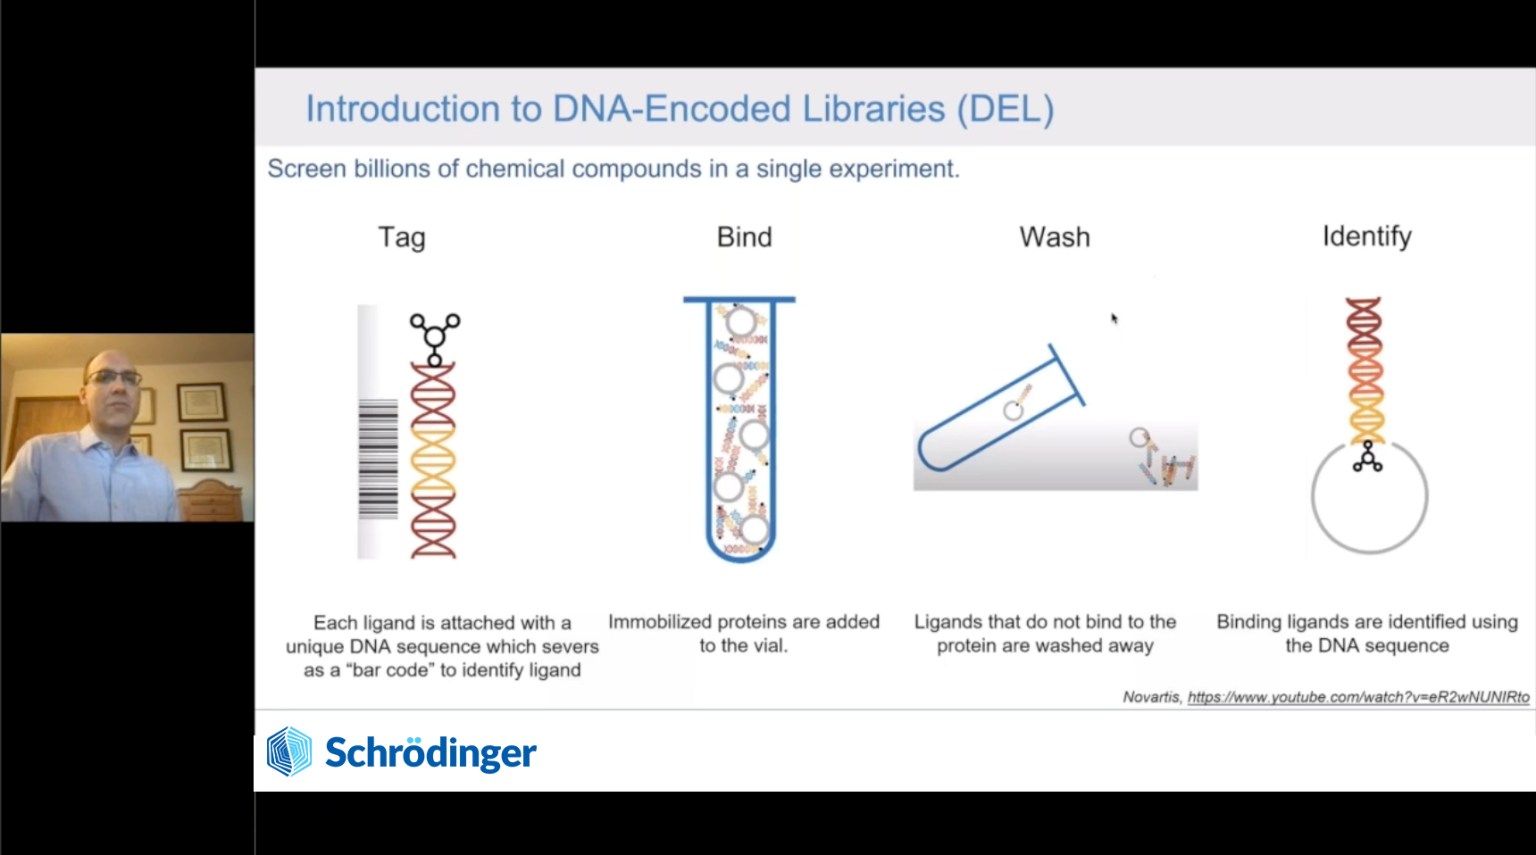
While traditional structure-based virtual screening has been successful in finding diverse hits to advance projects there is significant room for improvement of hit rates, diversity of hit chemotypes, available IP space explored, and the potency of unoptimized hits. Ultra-large, on-demand synthesizable libraries from vendors have enabled ~100x expansion of purchasable compound space, now billions of compounds, while DNA encoded libraries (DEL) can be even larger. In order to screen these much larger chemical spaces in the billions of compounds, results of two machine learning enabled approaches are described that make it easy and cost effective to find novel hits through virtual and DEL screens of billion compound plus libraries. DNA encoded libraries (DEL) enable screening billions of synthesized compounds but are limited due to high rates of experimental false negatives and positives. Employing machine learning trained to experimental DEL results we demonstrate significantly reduced false negative rates while identifying byproducts in a more favorable property space. To enable efficient, extrapolative chemical space exploration with an accurate docking scoring function, we have developed an active learning-based method employing AutoQSAR/DC machine learning and Glide SP docking as the learner. Results from Active Learning Glide screening of 100 million to billion compound screens show increased chemical diversity and GlideScore of hits relative to brute force screening of subsets of the libraries. Results and costs from these two new methods suggest billion compound library screens could replace smaller, traditional screens commonly employed today.
Taking experimentation digital: Materials innovation using atomistic simulation and machine learning at-scale
MAY 29, 2024
Taking experimentation digital: Materials innovation using atomistic simulation and machine learning at-scale
Our world is evolving rapidly and with it comes a wide range of challenges, including the need for sustainable and energy-efficient solutions, advanced electronic devices, and durable, lightweight materials for transportation, aerospace, and construction. Traditional methods for materials discovery or selection are no longer viable for keeping pace with demands.
In this talk, we will introduce a modern approach to materials R&D using a digital chemistry platform for in silico analysis, optimization, and discovery. The platform enables materials design at-scale across a wide range of applications, including organic electronics, catalysis, energy capture and storage, polymeric materials, consumer packaged goods, pharmaceutical formulation and delivery, and thin film processing.
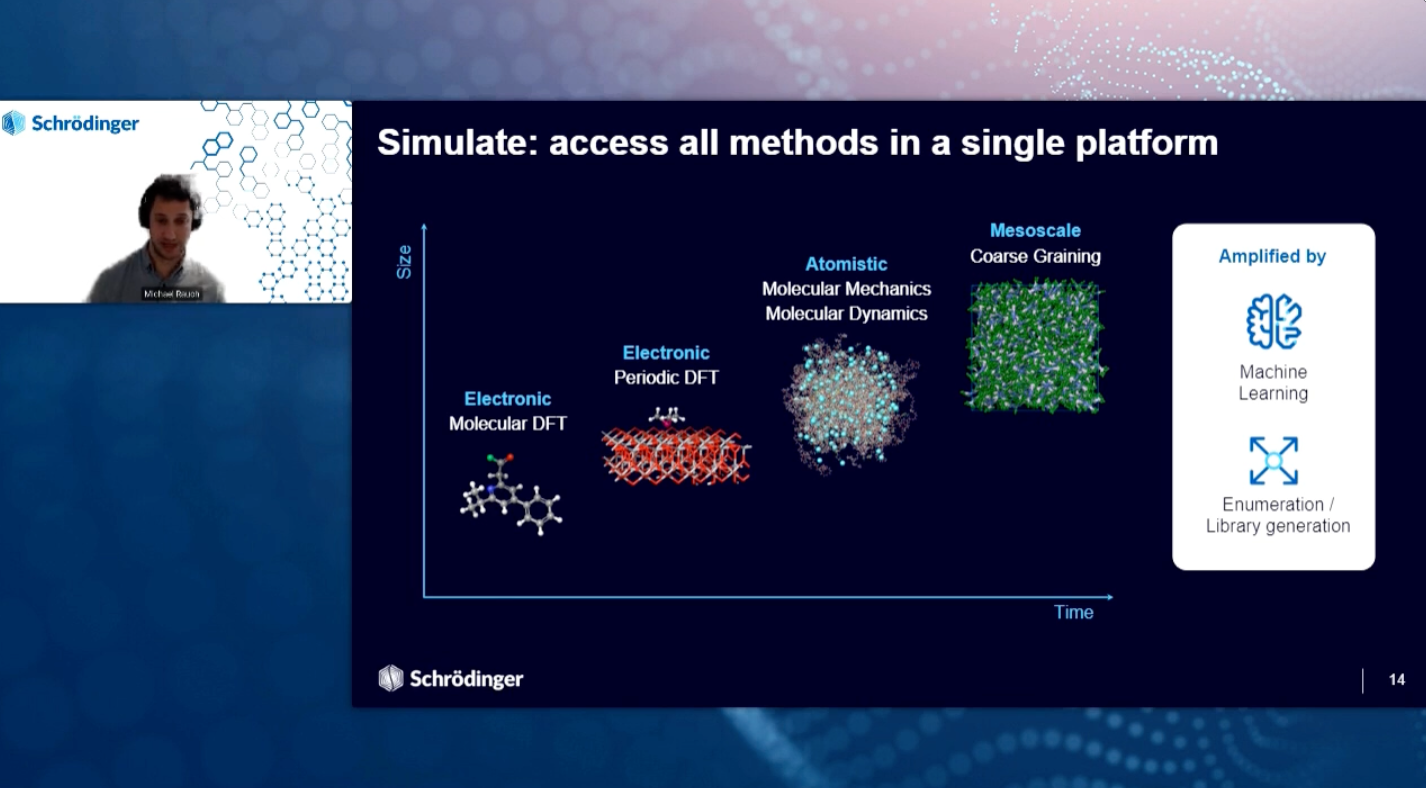
By combining both physics-based modeling approaches (e.g. DFT, molecular dynamics, coarse-graining) and machine learning, researchers can easily incorporate in silico methods into their day-to-day workflows to expedite R&D timelines. Moreover, automated solutions enable scaling from simple molecular property predictions on a local device to high-throughput calculations on the cloud.
We will present real-world case studies that were performed by both experienced modelers as well as novice experimentalists who are new to digital chemistry approaches.
Key Learning Objectives:
- Learn to leverage data from physics-based simulations and machine learning to accelerate materials R&D
- Hear practical case studies and customer stories across materials industries including organic electronics, catalysis, energy capture and storage, polymeric materials, consumer packaged goods, pharmaceutical formulation and delivery, and thin film processing
- Identify key areas in your R&D where physics-based simulation and machine learning can provide value
Michael Rauch, Ph.D.
Associate Director
Michael Rauch is an Associate Director at Schrödinger specializing in materials science and education. Michael earned his Ph.D. from Columbia University in synthetic organometallic chemistry as an NSF Graduate Research Fellow before pursuing a postdoctoral role in organic chemistry at the Weizmann Institute of Science as a Zuckerman Postdoctoral Scholar. Michael is particularly interested in green, sustainable chemistry and transforming the way that synthetic chemists utilize molecular modeling via practical education.